An AI content calendar prevents fragmentation by centrally recording brand identity, audience context, buying motivations and competitive differentiation, then translating every campaign theme from that foundation into channel-specific formats. Hard exclusions keep unsuitable claims and topics out before they are scheduled, while reviews, performance and human strategic approval inform the next planning decisions.
Key points of brand-safe AI content planning
Brand-safe automation does not begin with filling publication slots, but with the context and boundaries that determine which recommendations the calendar may make.
- Maintain one central message per campaign, but adapt the format and execution to the channel so variation does not lead to different positioning.
- Define in advance which claims, sensitive topics and competitor references must not appear in proposals; correcting them afterwards shifts risk and revision work downstream.
- Reorder topics and channel emphases when product delays, market movements or proven performance require it, without losing the coherence of the campaign theme.
- Evaluate vendors based on demonstrable governance in the workflow, not only on general statements about AI or brand safety.
- Measure efficiency across the entire chain: fast initial output is less valuable if the team must subsequently make extensive strategic corrections.
- Let AI analyse gaps and topic sequencing, but retain human strategic approval before the plan is executed.
Brand-safe calendar guidance starts before scheduling
A full AI content calendar is not automatically a brand-led calendar. Scheduling organises deadlines, campaigns and publication moments; brand-safe calendar automation determines earlier in the chain which recommendations are suitable at all. The distinction is practical: a plan can fill all available slots and still produce diverging emphases, wording and priorities. Once every channel choice arises solely from a local need, the organisation loses the central boundary within which the brand expression remains recognisable.
There is a real tension here. Full autonomy per channel creates room to tailor execution to its own distribution channel, but it can lead to fragmented brand expression. Rigidly uniform execution has the opposite drawback: content is then not sufficiently adapted to what a specific channel requires. The workable middle ground is not one identical format for every channel, but a central knowledge layer that keeps style boundaries central while enabling channel-specific formats. This allows execution to vary without the underlying positioning shifting by channel.
That central guidance cannot function as an unchanging set of calendar rules. Topics appear in a sequence, and channel emphases highlight particular parts of a campaign. If editorial review data shows that proposals consistently require adjustment, or if performance metrics demonstrate that an earlier emphasis is proven to be more effective, the planning engine must be able to process that information directly. Future topic sequences and channel emphases are then adjusted dynamically rather than fixed in a rigid schedule.
This shifts the test for an AI content calendar. The primary question is not how many items the system can schedule, but whether central brand boundaries already constrain the recommendation before an item appears as a campaign, channel or deadline decision. Reviews and performance then do not form a separate reporting layer alongside the calendar, but feedback for the next planning decisions. Scheduling only follows once this guidance determines what fits the brand context, chosen sequencing and channel emphasis.
One campaign theme, different formats without losing positioning
A campaign does not become consistent because every channel repeats the same content. Consistency arises when one overarching theme is retained as shared context while the execution changes by channel. A coordinated context engine can support that translation: for example, the same campaign theme can take the form of thought leadership on LinkedIn and a practical guide on the blog. The format differs, but the central message and brand positioning do not need to diverge as a result.
That distinction prevents a common confusion in campaign planning. Channel coordination does not mean that a LinkedIn post must be a shortened blog version, nor that a blog must conform to the rhythm of a social channel. Instead, the context engine preserves the connection between the individual formats. This enables the calendar to organise proposals as different contributions to one theme, rather than as a collection of independently selected topics. As a result, format variation has room without each channel implicitly formulating its own brand position.
A fixed quarterly plan gives production teams predictability. They can see in advance which themes, moments and dependencies are coming up. However, that stability has a limit when product delays or market movements make the original order less suitable. A static calendar then retains the old sequence because it was agreed earlier, even though the context may have changed that sequence. The question is therefore not whether a quarterly plan is useful, but whether the plan can reorder thematic dependencies when circumstances require it.
Automated sequencing can perform that reordering without losing context. In the event of a delay or market movement, a topic does not simply need to disappear from the calendar or be moved independently to a later slot. Its relationship to the campaign theme and the other channel executions remains the starting point for the new order. This allows content teams to retain both a predictable planning foundation and the ability to adapt execution when priorities change.
For evaluating an AI editorial calendar, the core therefore lies in the quality of that context translation. The solution must be able to show that it consistently applies one campaign theme across varied channel-specific formats and that it preserves thematic coherence during reordering. A sequence of scheduled publications alone does not make that connection visible.
Sources for this section: contentmarketinginstitute.com
Without hard exclusions, risky proposals end up in review
An instruction for reviewers to watch for brand-sensitive or inaccurate proposals is different from a rule that keeps such proposals out of a calendar in advance. With an AI content calendar, that difference emerges before an editor sees an item. If a proposal is generated first and only assessed for risk afterwards, responsibility lies with a manual review cycle. A hard exclusion rule acts earlier: it limits which claims, topics and competitors may appear in the proposal.
Deterministic validation rules and exclusion filters, also known as negative guardrails, are a demonstrably testable component of planning logic. They can keep prohibited claims, sensitive topics and competitors out of calendar proposals. The word “hard” matters here: the rule is not a non-binding preference that can be interpreted differently during review, but a predefined exclusion. For a product evaluation, this means that a vendor must not only make a general promise about brand safety, but must be able to demonstrate support for this specific form of validation.
Without such rules, the risk increases that unvalidated or misleading claims will enter the calendar. That risk does not stop with the individual calendar item. A proposal that initially appears ready for production may later still create regulatory risk. The calendar then does not establish a clear production path, but moves the assessment to a point when the topic, sequence and campaign alignment may already have been prepared.
The organisational consequence is at least as relevant. Legal teams and executive teams can block AI marketing initiatives when the process provides insufficient protection against unvalidated or misleading claims. Even without a direct block, initiatives can become bogged down in slow manual review cycles. The delay does not arise because review is unnecessary, but because reviewers repeatedly need to catch proposals that should never have appeared in the plan.
This also changes the role of editorial review. Reviewers can focus on substantively assessing proposals that fall within predefined boundaries, rather than repeatedly having to correct the basic admissibility of claims, sensitive topics or competitor references. A calendar with exclusion filters does not promise that all risk disappears. It does prevent the first selection from already depending on after-the-fact correction, even though that first selection determines what the organisation must subsequently discuss, check and potentially block.
Sources for this section: wfanet.org, adassoc.org.uk
What a vendor demo must demonstrate about governance
A vendor demo should distinguish between broad AI adoption and demonstrable governance in calendar planning. The matrix below focuses the assessment on evidence a solution can provide, rather than general statements about brand safety.
| Criterion to assess | Appropriate evidence in the demo | Why this makes a distinction |
|---|---|---|
| Formal Responsible AI framework | Show that a formal framework has been operationally implemented, rather than existing only as policy or ambition. | Among major advertisers, 63% to 75% use or plan to use generative AI. That usage alone says nothing about the presence of a functioning governance framework. |
| Brand safety as a separate assessment criterion | Ask how the solution substantiates brand safety within planning and which formal setup is visible. | 80% report serious concerns about brand safety. The concern is therefore widespread, but it is not the same as evidence that a calendar solution addresses it operationally. |
| Operational implementation, not just adoption | Ask which part of the Responsible AI setup actually functions in the workflow. | Only 27% to 44% have operationally implemented formal Responsible AI frameworks. The gap between usage and implementation makes a concrete demonstration more relevant than a general product claim. |
| Conformity with recognised guidelines | Request demonstrable conformity with the WFA Responsible AI Principles and the best practices of the Advertising Association and ISBA. | This conformity is an assessment signal for responsible AI adoption. It provides a testable basis for comparing vendors, without suggesting that conformity with guidelines removes every brand or compliance risk. |
Sources for this section: aana.com.au
Test whether speed creates revision work before or after the calendar
The trade-off around content calendar automation is not only about how quickly the first calendar appears. This test sequence reveals whether speed reduces work at the beginning of the process or merely moves revision work to a later point.
- Start with the basis for filling slots. A generic one-click calendar can fill dozens of slots very quickly based on search volumes. This is a direct form of speed: the calendar quickly looks complete and immediately provides a list of topics. However, the question for the evaluation is what this input says about the usability of the proposals. Search volumes are the basis for filling slots here, not a strategically configured context.
- Then assess the revision burden after the initial output. The fast generic calendar may require significant revision time afterwards. A filled calendar is therefore not automatically a ready-to-use plan. When the team must still substantively adjust every slot to arrive at a usable calendar, the speed is mainly concentrated before the review phase. The assessment should therefore not stop at the number of generated slots, but at the amount of correction still required afterwards.
- Make the initial setup explicit. A platform with a required strategic knowledge layer requires a setup investment. This is not a disadvantage that falls outside the comparison; it is precisely the investment that precedes calendar output. The relevant question is whether this setup demonstrably serves to produce immediately usable, differentiated calendars. An evaluation that only measures time to first output leaves this shift in work out of view.
- Compare where the work occurs, not only the speed of the interface. With one-click output, the focus is first on quickly filling slots and then on potentially extensive revision. With a strategic knowledge layer, part of the work occurs upfront in the setup, with the intended outcome of a calendar that is immediately usable and differentiated. These are two different process forms. The first maximises early output; the second connects setup to the quality of the calendar received by the editorial team.
- Frame the outcome as an operational choice. A calendar only deserves to be called efficient when the team can identify where revision time ends up. If the first output is fast but later requires extensive revision, the workload has merely shifted. If an initial setup investment results in immediately usable and differentiated calendars, speed is distributed differently across the planning chain.
Full autonomy or human-in-the-loop for brand-sensitive planning?
Full autonomy is not a requirement for an efficient AI content calendar. The choice concerns the division between automated planning analysis and human responsibility for strategic approval.
- Must an AI content calendar publish fully autonomously to be efficient?
No. Fully autonomous publication may minimise staffing costs, but it introduces brand liability and compliance risks. Savings in human effort are therefore only one side of the trade-off. When the calendar proceeds to publication without human intervention, strategic approval disappears from the planning chain while responsibility for brand and compliance remains. - What is the alternative to a set-and-forget model?
A human-led loop. In this setup, AI performs gap analysis and topic sequencing, but human strategic approval takes place before the plan serves as the basis for execution. Automation and human assessment do not exclude one another here: the former supports analysing gaps and the order of topics; the latter keeps strategic responsibility explicitly in the chain. - Which tasks fit within automated planning?
Gap analysis and topic sequencing fit within the AI role described by this setup. Gap analysis focuses on identifying gaps; topic sequencing on ordering topics. This allows the calendar to be prepared without equating human strategic approval with manually performing all planning. The human step occurs at the point where the proposed direction is assessed as strategically acceptable. - Why does strategic approval remain relevant if the analysis is automated?
The trade-off makes this clear. A fully autonomous process reduces staffing costs, but increases risk around compliance and brand liability. A human-led loop accepts that strategic approval remains a separate step, while AI performs the preparatory analysis and ordering work. Responsibility is therefore not implicitly hidden in an automated publication flow. - Does human involvement mean AI adds little value?
No. Its added role lies precisely in performing gap analysis and topic sequencing under human strategic approval. The relevant boundary is not autonomy versus no automation, but automated analysis with a clearly designated point at which the organisation assesses the strategic direction.
The decisive boundary lies in demonstrable brand context
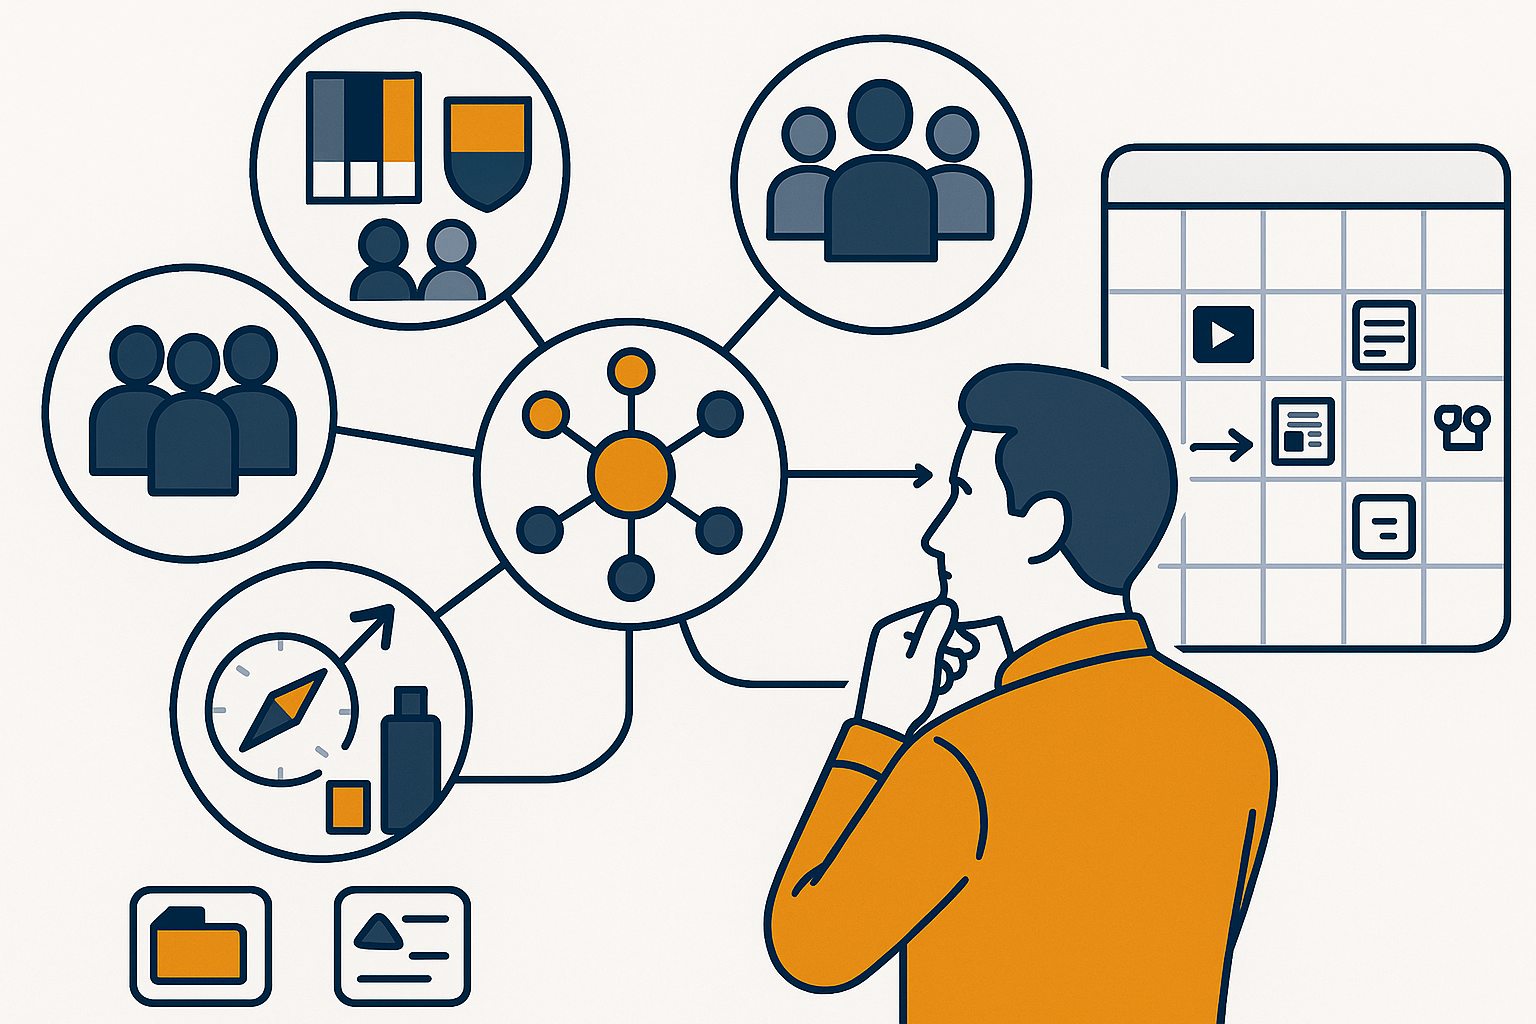
The selection question for an AI content calendar can be reduced to one verifiable point: where and how is the brand and market context that guides recommendations recorded? Speed, channel variation, exclusions and strategic approval only gain meaning when the underlying context is centrally available to planning. Otherwise, a team assesses individual proposals, but not the foundation on which those proposals are repeatedly produced.
A central relational knowledge layer, or knowledge graph, is a concrete selection signal for this. In that layer, brand identity, ICP profiles, buying motivations and competitive differentiation are embedded in machine-readable form. These components are then not scattered as occasional explanations around individual calendar prompts. They form a structured foundation that recurring recommendations can rely on. During selection, the test is therefore not whether a vendor says it uses brand context, but whether these four forms of context are demonstrably present in such a central layer.
This distinction also has operational consequences. When recommendations remain dependent on individual prompts, context can be provided differently, omitted or interpreted differently for each task. The calendar then has no demonstrably stable basis for recurring recommendations. This creates a risk of additional review work and planning decisions that do not rest on the same brand and market reference, with associated operational costs when proposals need to be reassessed or adjusted.
A structured knowledge layer does not replace human strategic approval. It does make visible which context supports the recommendation, so that approval can concern an explicit and repeatable foundation. The concrete limitation remains: an assessment dependent on individual prompts provides no demonstrably stable basis for recurring calendar recommendations.